Implementing Cloudflare Workers AI JSON Schema
Learn how to reliably implement schema-constrained JSON outputs in Cloudflare Workers AI by managing model capabilities, validation, and fallback logic.
Curated technical articles, architecture patterns, and practical guides covering Serverless on RayLabs (23 approved articles).
Learn how to reliably implement schema-constrained JSON outputs in Cloudflare Workers AI by managing model capabilities, validation, and fallback logic.
Learn how to manage uncertain email delivery states during timeouts by implementing a local idempotency ledger and leveraging provider-specific keys.
Learn how to retry a failed AI draft without consuming a valid workflow source by separating source validation from model output validation in serverless pipelines.
Learn how to optimize targeted workflow runs by explicitly skipping the revision-discovery phase when processing new source cards, ensuring your pipeline remains efficient and focused.
Learn how to scope your Cloudflare Workflow runs to a specific source reference, preventing unintended modifications to unrelated article drafts in your queue.
Learn how to normalize structured JSON responses from Cloudflare Workers AI to ensure compatibility with downstream parsers and prevent serverless workflow failures.
Learn how to revalidate persisted Cloudflare Workflow step outputs after code changes so newly tightened input contracts apply safely during both fresh execution and durable replay.
Learn how to build a read-only operator dashboard for serverless publishing workflows on Cloudflare Workers without risking duplicate runs.
Learn how to select a specific queued article revision using a validated path without widening your bounded queue scan or bypassing review guards.
Reserve publication reads before background queue cleanup to prevent request budget starvation in a serverless publishing workflow.
Examine why manual parent workflows fail at child boundaries when custom instance identifiers violate downstream prefix assumptions, and learn how to validate platform IDs safely.
Learn how to preserve a serverless publishing workflow draft when request limits prevent same-run publication by deferring publication.
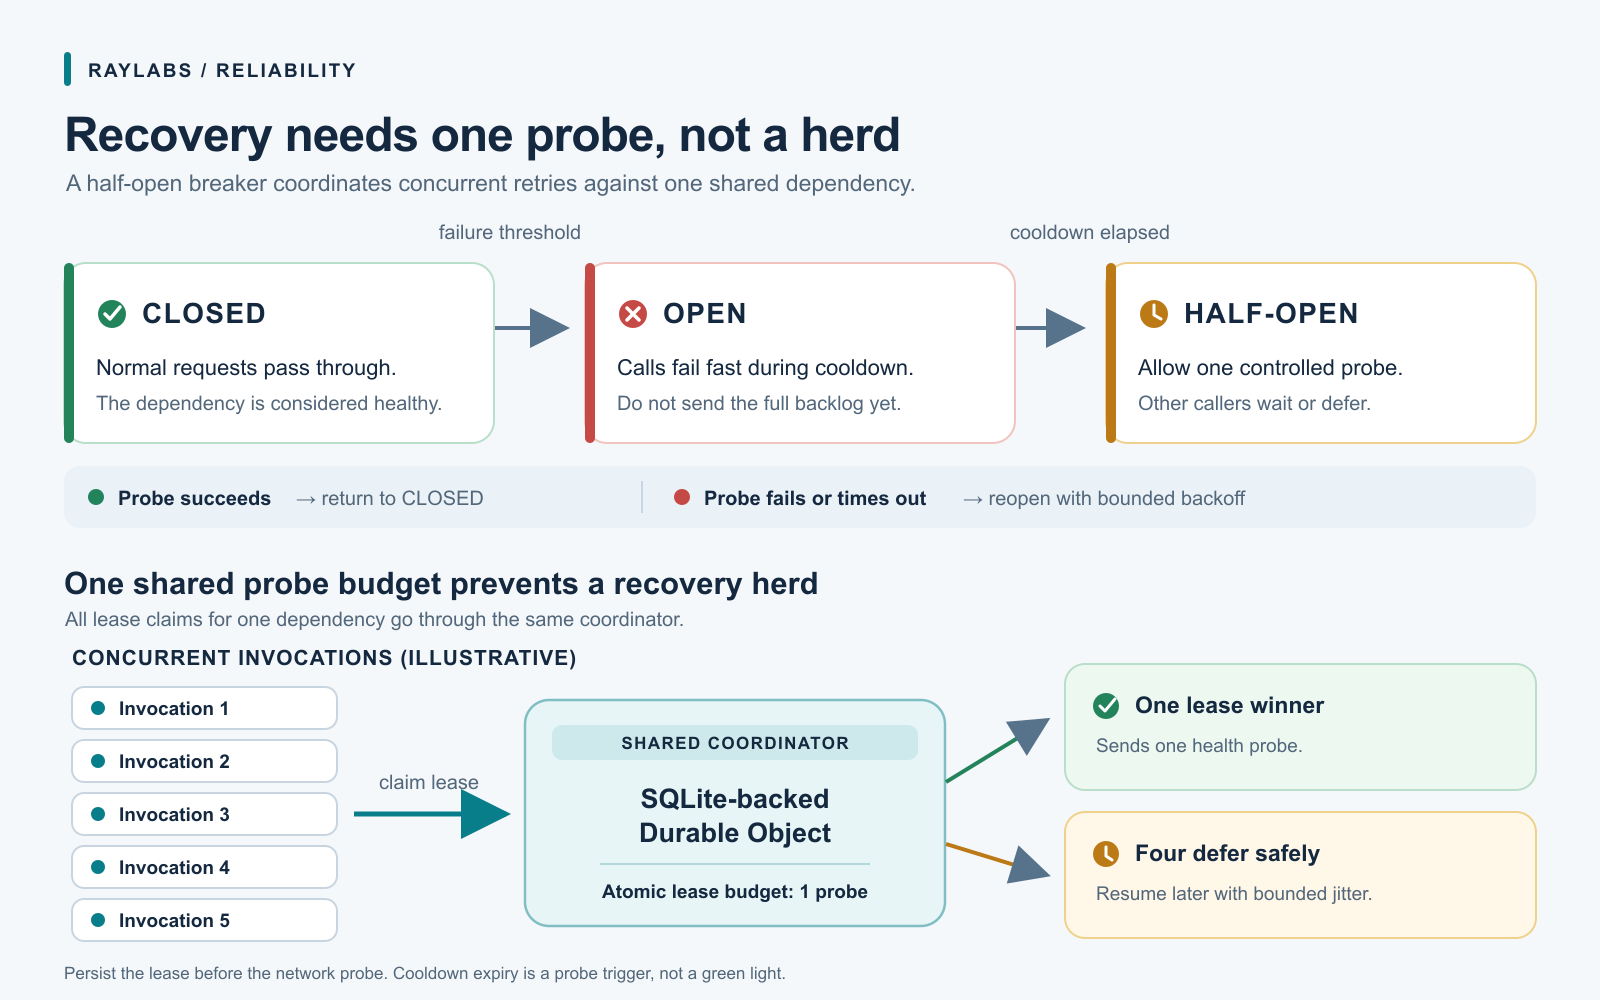
Learn how to prevent thundering-herd recovery in serverless workers by coordinating half-open circuit breaker probes through a SQLite-backed Durable Object instead of eventually consistent key-value stores.
Learn how to separate text-generation fallbacks from visual review gates in serverless AI pipelines so that image verification fails closed instead of running on text-only models.
Learn how to build a reliable scheduled digest email for high-frequency serverless cron systems, featuring local-timezone logging, fallback raw-stats reporting, and advisory-only recommendations.
Learn how to build bounded LLM fallback chains that prevent cost overruns, respect rate limits, and stop on billing errors.
Learn how to host multi-image Threads carousels directly inside a Cloudflare Worker using KV storage, bypass external object storage, and manage the publishing pipeline.
Learn how to keep an LLM fallback tier proven with async shadow traffic, response-shape contracts, and scheduled failover drills.
Learn how to design self-clearing kill switches that prevent transient outages from turning into persistent pager events, alongside human-readable failure reports that replace raw JSON dumps.
Learn how to diagnose and fix media publishing failures caused by edge key-value storage propagation delays when third-party platforms fetch newly uploaded files.
Learn how to calculate true scheduled publishing reliability by anchoring your denominator to cron slots and verifying user-visible outcomes rather than trigger attempts.
Learn how to keep read-only demand signals flowing in unattended cron workers while a kill switch blocks all write operations.
Learn how to distinguish Gemini API geo-blocking from server overload when calling from Cloudflare Workers egress IPs, and discover the exact response handling strategies needed for each.